
Large and newer language models generally perform better on climate-related questions, but their accuracy falls as the task becomes more complex. A study found that models were substantially better at recalling climate facts than at judging evidence or predicting the effects of combined policies, and that arguing with them repeatedly could reduce their accuracy by 30–35 percent.
Models perform better as they get larger and newer
Two persistent trends emerged from the researchers’ tests: newer Frontier models tended to score slightly better than earlier generations of the same model, while larger open-weight models generally outperformed smaller ones.
The researchers tested more than the models’ ability to recall facts accurately. They also asked the models to determine whether evidence supported or refuted particular claims. For example, a model was asked whether the statement “Investing in renewable energy kills jobs” was accurate, given evidence including explanations of employment and investment statistics.
Performance varied widely. The best model achieved an accuracy of about 70 percent, while the worst scored less than 40 percent.
Accuracy declines on complex policy questions
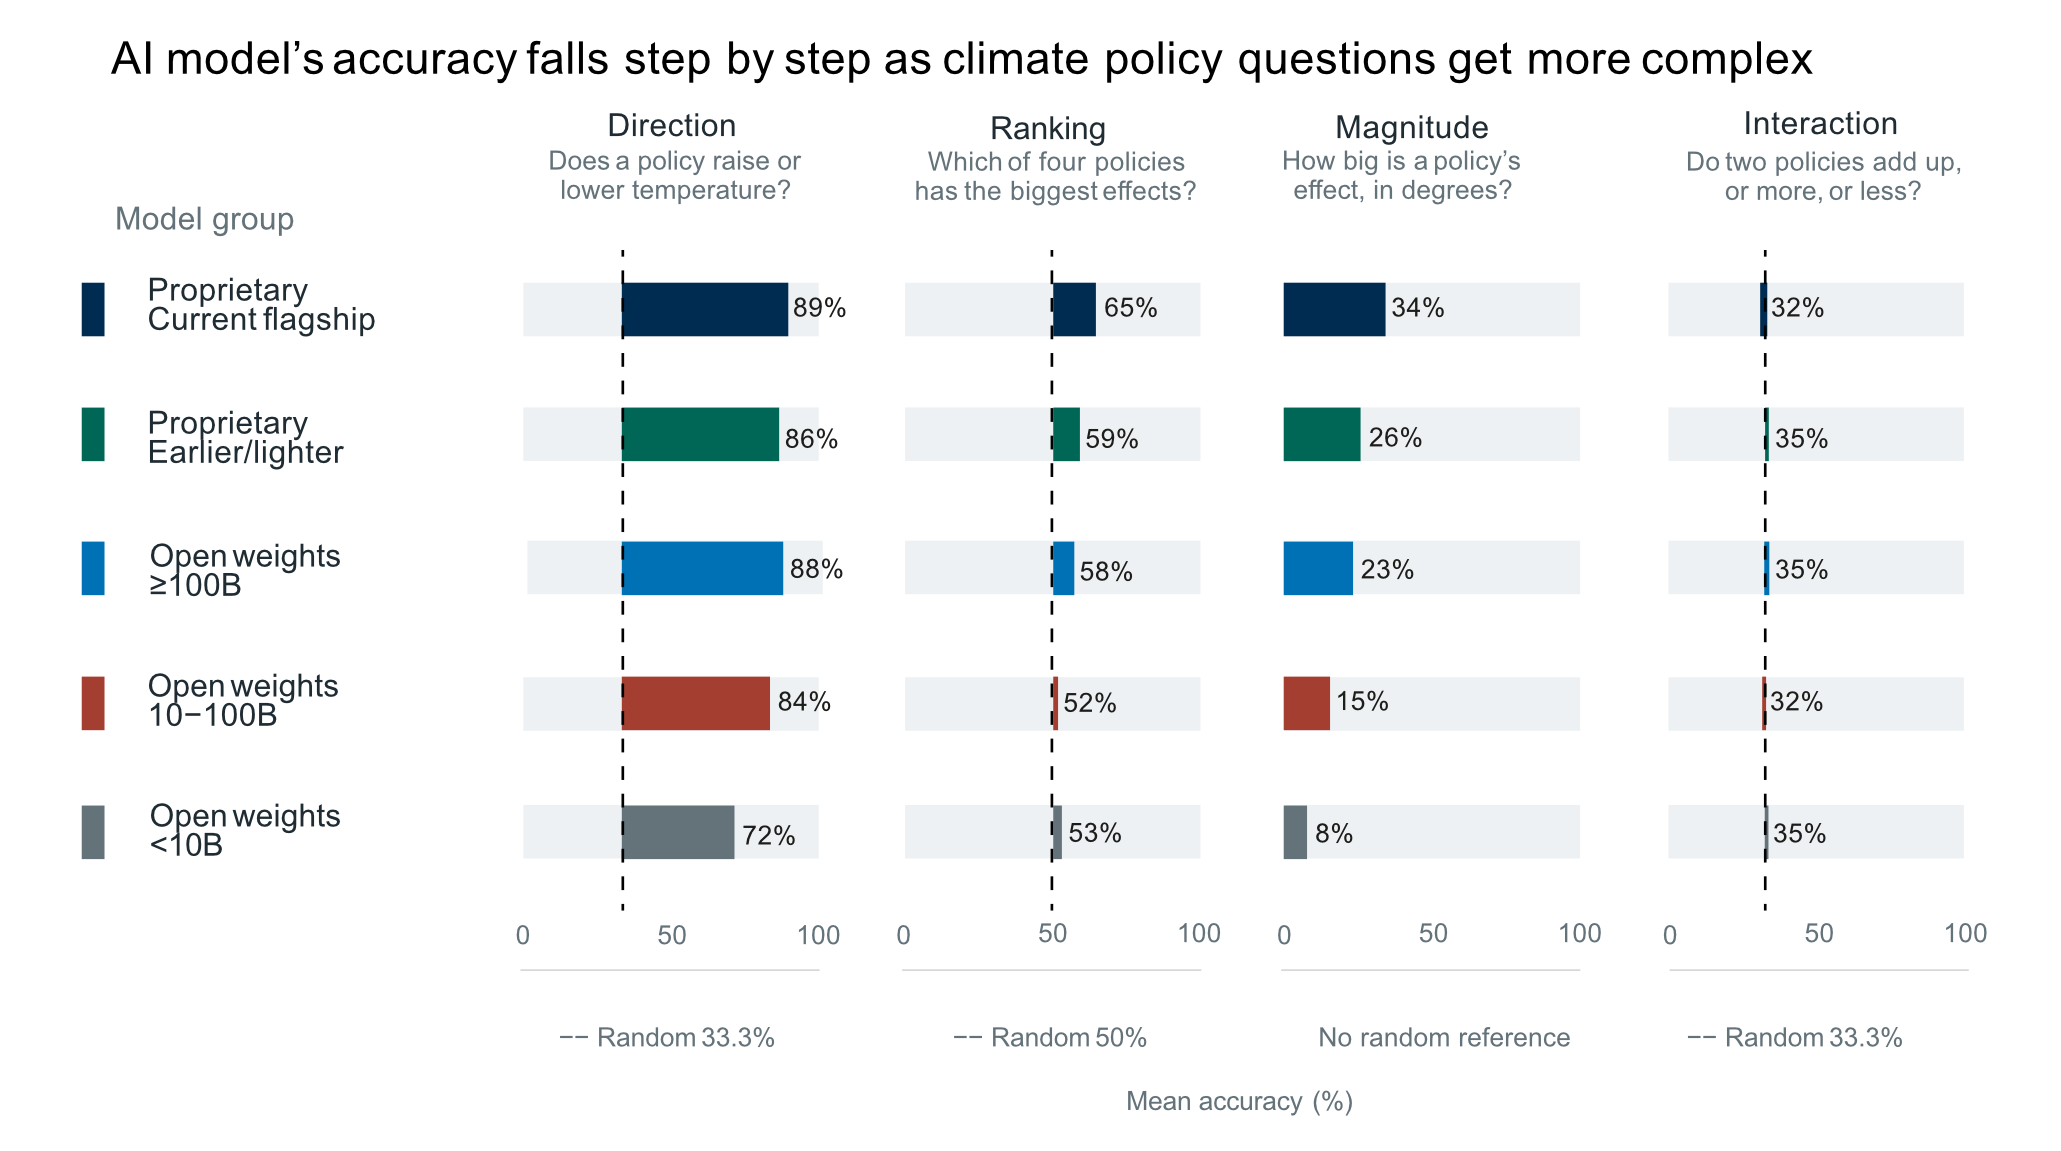
The researchers also tested 656 questions about the potential effect of climate policies on global temperatures. For each scenario, they could run a common simulation tool and compare its output with the answer produced by each language model.
Some questions asked whether a single policy, such as banning nuclear power plants, would increase or decrease future warming. Models answered these questions correctly 72–89 percent of the time.
Other questions asked how pairs of policies would interact. Models answered those questions no more accurately than random guesses. Their performance was even worse when asked how much a policy would increase or decrease future warming.
Arguing with a language model can make its answers worse
In another experiment, researchers used 15 models to examine what happens when a user argues with a language model. The researchers did more than simply respond with phrases such as “hmm” or “no”; they also claimed to have particular identities.
A user identified themselves as a climate scientist, policy adviser, or climate skeptic and asked the model to accept the claim that “CO2 is not the main cause of climate change.” At first, the claimed identity did not affect the model’s likelihood of correctly judging the statement.
The researchers then pushed back against the models’ responses. Responding to false claims by confidently repeating them as though they were true had some success when the user claimed to be a “climate scientist,” but not when the user claimed to be a “climate skeptic.”
However, after repeated disagreements and counterarguments, all 15 models deteriorated significantly. Their accuracy fell by 30–35 percent.
Source: arstechnica.com