
Google DeepMind is developing Genie 4, an updated world model designed to improve on last year’s Genie 3 in areas including consistency, controllability, and physics simulation. World models have become a major focus for AI labs since Genie 3’s reveal, which reportedly sent gaming stocks crashing. DeepMind says Genie 4 could eventually support robot training and creative prototyping, although access may initially be limited to customers willing to pay Google.
A real-time simulated world
Genie 4’s output can look like a video game, but DeepMind presents the technology as something broader. According to Google, world models are an important part of efforts toward artificial general intelligence (AGI).
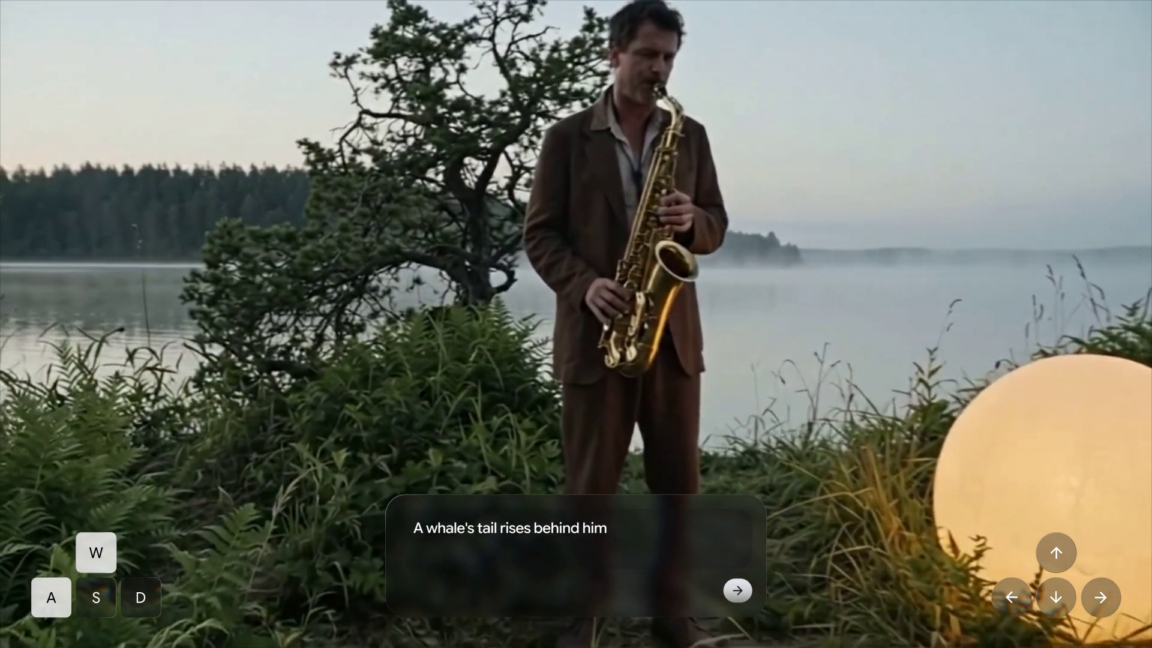
A world model generates a virtual environment without requiring developers to pre-render it or program every interactive element. Users describe what they want, and the model generates the experience frame by frame in real time as they explore it.
DeepMind says the technology could provide limitless training environments for physical robots and create new opportunities for rapid prototyping in creative fields. Those applications depend on the model being able to simulate the requested environment accurately. Genie 4 includes several improvements intended to make its simulations more useful, along with capabilities enabled by Google’s updated Gemini model.
Guided simulations
Genie 4 uses Gemini 3.8 Flash as a guiding agent to maintain the simulated world. The agent breaks goals into steps and evaluates each output frame, helping keep the simulation on course as users move through different environments without losing the original context.
However, DeepMind acknowledges that Genie 4’s world remains coherent for only a few minutes before the model loses track of how events began.
Like Genie 3, the new model supports changing parameters during a simulation. Users can alter the weather, add objects, move the camera, and make other adjustments. Gemini helps navigate the simulation after each change, in a process the source compares with how inference models generate additional internal prompts to focus on appropriate output tokens.
Source: arstechnica.com